Google Scholar is a reliable source of research data and information for R&D teams. With its advanced search capabilities, comprehensive indexing of scholarly literature, and a vast range of resources available to researchers, Google Scholar can be an invaluable tool in the pursuit of innovation. But how reliable is Google Scholar?
This blog post will explore what makes Google Scholar so reliable by examining how it works, exploring its advantages and disadvantages as well as looking at alternative sources that may provide comparable results. Whether you’re an experienced researcher or just getting started with your project, understanding the reliability offered by Google Scholar is essential to ensure successful outcomes from your work. So let’s answer: how reliable is Google Scholar?
Table of Contents
How to Use Google Scholar Effectively
Advantages of Using Google Scholar
Disadvantages of Using Google Scholar
Alternatives to Google Scholar
Conclusion: How Reliable Is Google Scholar?
What Is Google Scholar?
how reliable is Google Scholar? Google Scholar is a free search engine developed by Google that enables users to find scholarly literature from journals, books, and other sources.
Google Scholar offers a vast selection of scholarly works, including journal articles, conference papers, theses, dissertations, and preprints. Google Scholar is widely used by researchers due to its sophisticated algorithms and comprehensive selection of scholarly material from various sources.
Google Scholar’s accessibility and availability provide a major benefit to researchers. With its powerful algorithms and comprehensive coverage of academic literature across all disciplines, it offers open access to millions of documents from different sources including open-access repositories like PubMed Central or arXiv – something that traditional library databases can’t offer.
With its user-friendly interface, Google Scholar enables researchers to quickly refine their searches based on various criteria such as author name or publication year, thus optimizing the research process.
Verifying the accuracy and reliability of sources can be a challenge when using Google Scholar, due to its lack of editorial oversight on many documents indexed. In addition, it only provides access to a limited number of sources compared with more comprehensive search engines like Scopus or Web Of Science. Although these may require payment for full-text access.
Google Scholar is a powerful tool for research and innovation teams to quickly access relevant information. By understanding how to use Google Scholar effectively, you can maximize its potential in your research process.
Key Takeaway: Google Scholar is a powerful search tool that offers unrestricted access to vast amounts of data from diverse origins, thus rendering it an invaluable asset for researchers. However, the accuracy and reliability of some indexed materials may be questionable due to their lack of editorial oversight and limited source accessibility.
How to Use Google Scholar Effectively
How reliable is Google Scholar? We can make it reliable by learning how to use it effectively. Using Google Scholar effectively can be a game-changer for R&D and innovation teams.
Getting set up with an account is the initial step for utilizing Google Scholar efficiently, taking only a few moments of your time. Once you have set up your account, Google Scholar’s extensive resources will be available to you.
To begin searching for relevant information, use keywords that are related to your research topic or question. You can also refine your results by using advanced search options such as language, author name, and year of publication if needed. Keeping track of all the sources you find during this process is essential to avoid duplicating work and ensure accuracy in citations when writing reports or articles later on.
Google Scholar’s convenience and breadth of resources, providing access to thousands of scholarly articles from various disciplines worldwide with just a single click, make it an ideal tool for researchers at all levels. Furthermore, its user-friendly interface makes navigation easy even for those who may not have had much experience with online databases or search engines – making it ideal for researchers at all levels.
In addition, its comprehensive coverage includes both peer-reviewed journals as well as books and conference proceedings. This ensures that no source goes undiscovered during your research process.
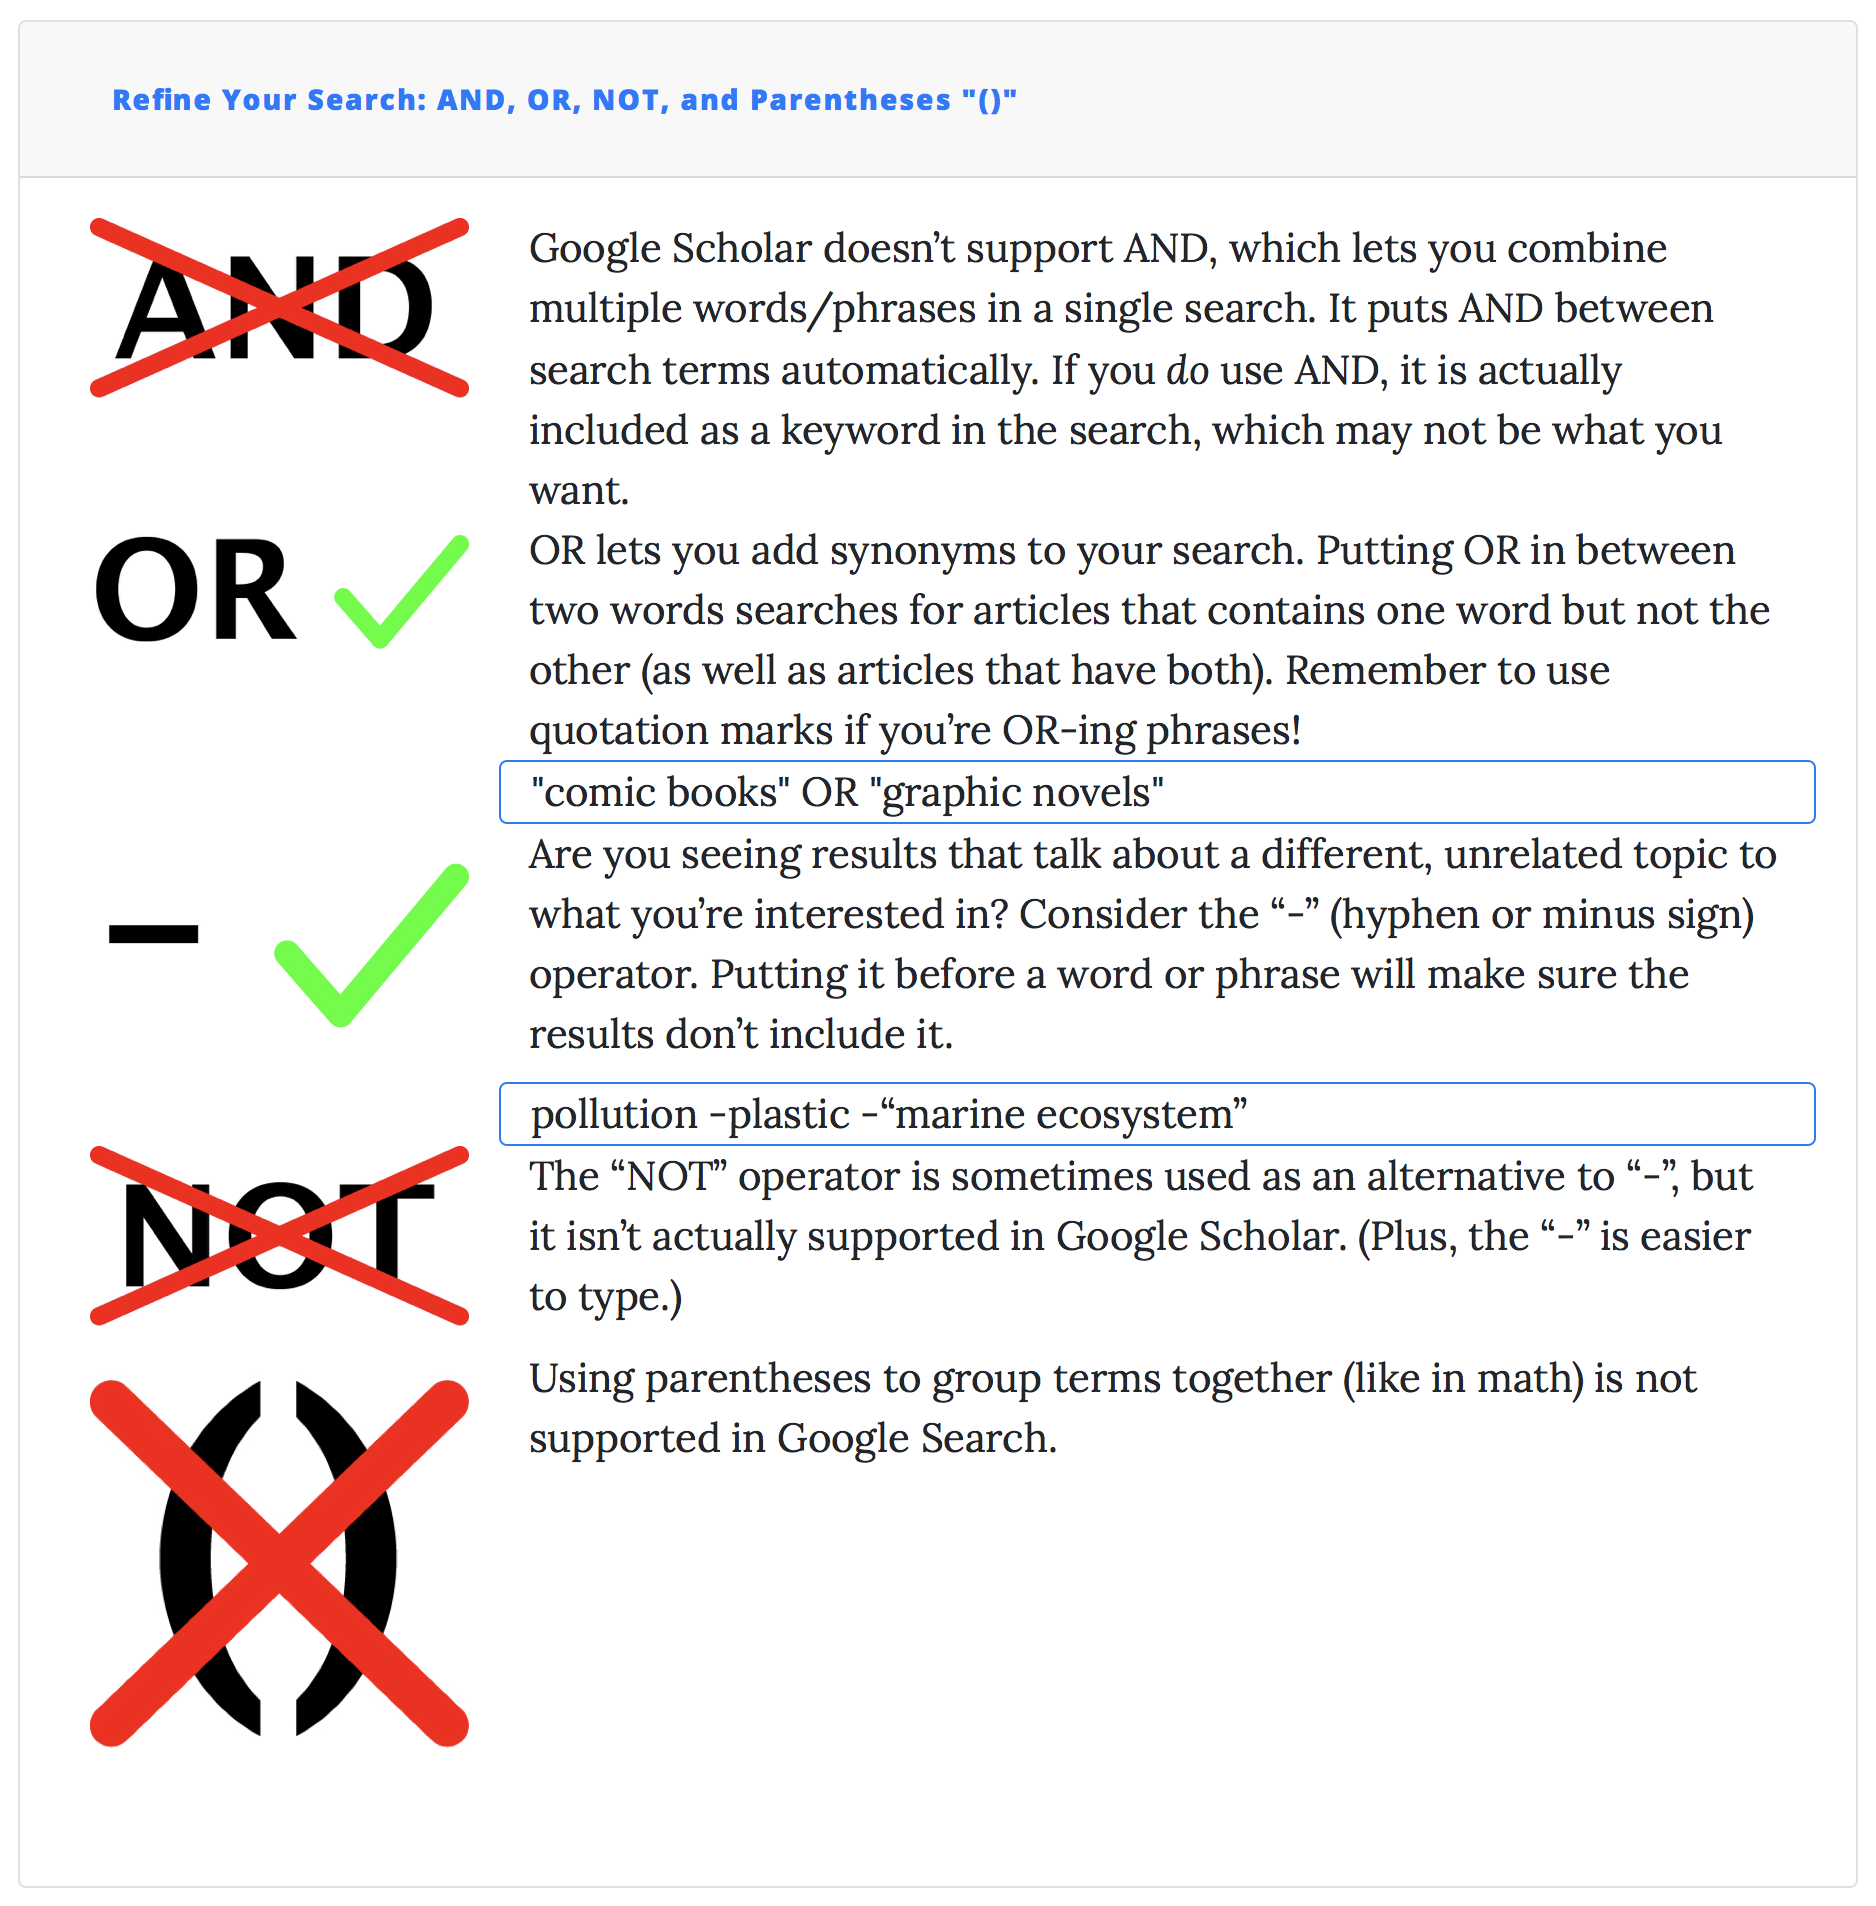
(Source)
Unfortunately, there are some limitations associated with using Google Scholar. This is primarily because many universities do not provide full-text access so finding complete versions can be difficult sometimes (unless they are open access).
Additionally, since most content indexed by Google scholar comes from external websites there’s always a risk involved regarding verifying accuracy and reliability, especially when citing sources in publications or reports. Lastly, a limited number of sources available could lead researchers towards missing out on important references while conducting their research projects thus hampering progress significantly over time.
Alternatives exist if you need more specific material than what’s offered through Google Scholar alone. This includes academic search engines like Scopus and Web of Science as well as library databases such as JSTOR and ProQuest. There are also open-access journals like PLOS ONE and BMC.
Each platform offers unique advantages depending on what kind of data/information one needs exactly, so make sure to explore them thoroughly before deciding which option best suits individual requirements.
Using Google Scholar effectively can save time and effort when researching topics. With its comprehensive coverage of academic literature, it is a valuable tool for R&D teams to have in their arsenal. By taking advantage of the advantages discussed above, research teams will be able to quickly access relevant information and refine their results with ease.
Key Takeaway: Google Scholar is a great asset for R&D and innovation teams, providing easy access to thousands of scholarly articles from all over the world. Although it has its limitations such as not having full-text access or difficulty verifying accuracy and reliability, there are plenty of other search engines available which can be explored depending on individual requirements. All in all, Google Scholar is an invaluable tool that shouldn’t be overlooked when conducting research.
Advantages of Using Google Scholar
Google Scholar is a powerful tool for research and innovation teams, offering comprehensive coverage of academic literature from various sources. Google Scholar enables research and development teams to remain abreast of the most recent advances in their field, providing access to a broad range of scholarly literature. Users can quickly locate pertinent data that satisfies their requirements through the user-friendly interface.
One of the main advantages of using Google Scholar is its availability and accessibility of resources. Google Scholar offers an extensive selection of resources, such as books, journals, articles, and conference proceedings which makes it a valuable research tool.
Furthermore, these resources are easily accessible as they are available online with just a few clicks away; this saves time and effort when searching for information. Google Scholar has been designed with simplicity in mind, making it easy for even those unfamiliar with search engines to use.
Another advantage offered by Google Scholar is its comprehensive coverage of academic literature across different disciplines such as science and technology, engineering and medicine, and others, thus providing valuable insights into current topics within each field or area of study.
This helps researchers stay updated with the most recent advancements in their fields while also giving them access to other related topics that could help broaden their understanding further on certain subjects or domains. Additionally, through advanced search options like filtering by author name or publication year, users can refine results according to specific criteria which makes finding relevant information easier and more efficient.
How reliable is google scholar? Overall, Google Scholar provides a convenient and accessible platform for researchers to access an abundance of academic literature. Despite its benefits, Google Scholar also has some potential drawbacks that should be considered before use; these will be explored further in the following section.
Key Takeaway: Google Scholar is a go-to platform for research and innovation teams, offering easy access to an extensive range of academic literature. It provides users with the latest information in their field through its user-friendly interface, while also allowing them to refine results by author name or publication year making it easier to find relevant data quickly and efficiently.
Disadvantages of Using Google Scholar
Though its usefulness is undeniable, one must be aware of certain drawbacks when using Google Scholar for research.
One of the main disadvantages of using Google Scholar is the limited number of sources available. While it does have an extensive collection, it only includes certain types of content such as journal articles, books, conference papers, and patents.
This platform may not provide access to other types of materials such as periodicals or magazines. Additionally, many databases are not included in Google Scholar’s search engine which can make finding relevant information more difficult than if you were searching on another platform such as Academic Search Engines or Library Databases.
Another disadvantage of using Google Scholar is verifying the accuracy and reliability of sources found within its database. Since anyone can upload their work for Google Scholar indexing, there’s no assurance that all results are valid or dependable since they have not been verified by specialists in the field before being posted online.
Therefore, users must take extra caution when evaluating results from this platform before relying on them for research purposes or making any decisions based on these findings.
How reliable is Google Scholar? Overall, it is clear that Google Scholar has some disadvantages when used as a research tool. Therefore, researchers should consider other alternatives to find reliable sources of information for their projects.
Key Takeaway: Google Scholar provides a wealth of academic literature, but is limited in its scope and reliability. Users should be aware that not all sources indexed by the platform have been vetted or verified for accuracy. Thus extra caution must be exercised when evaluating results from Google Scholar to ensure reliable research findings.
Alternatives to Google Scholar
There are other search engines and databases that can provide more comprehensive coverage of academic literature than Google Scholar. Scopus and Web of Science offer researchers a wealth of peer-reviewed journals, conference papers, book chapters, and other scholarly material. Library databases like JSTOR and ProQuest also provide access to scholarly resources from leading publishers in the humanities, sciences, social sciences, and business disciplines.
Open Access Journals such as PLOS ONE or BMC are freely available online publications with content that is published under an open license allowing readers to use the material without any restrictions. These alternatives offer researchers greater control over their searches by allowing them to refine their results according to specific criteria (e.g., publication date range).
Open Access Journals like PLOS ONE or BMC offer users the opportunity to store their searches, permitting them to monitor their progress on a given topic or research project throughout its duration. By taking advantage of these tools researchers can get better insights into the topics they’re researching while ensuring accuracy and reliability in their sources at the same time.
Research smarter, not harder. Take advantage of reliable alternatives to Google Scholar like Scopus, Web of Science & Open Access Journals for comprehensive coverage and better insights. Click to Tweet
Conclusion: How Reliable Is Google Scholar?
How reliable is Google Scholar? While it has some disadvantages such as its inability to provide full texts of articles or the need for manual sorting through results.
Overall, Google Scholar provides an invaluable resource that can be used in combination with other tools to maximize the efficiency of any team’s research process. With careful consideration and the use of alternatives when necessary, Google Scholar can help your team make informed decisions quickly and reliably.
How reliable is Google Scholar? Discover the reliability of Google Scholar with Cypris, a research platform designed to provide rapid time-to-insights for R&D and innovation teams. Uncover valuable insights quickly and efficiently by centralizing data sources into one comprehensive platform.
How Reliable is Google Scholar for Research?


Google Scholar is a reliable source of research data and information for R&D teams. With its advanced search capabilities, comprehensive indexing of scholarly literature, and a vast range of resources available to researchers, Google Scholar can be an invaluable tool in the pursuit of innovation. But how reliable is Google Scholar?
This blog post will explore what makes Google Scholar so reliable by examining how it works, exploring its advantages and disadvantages as well as looking at alternative sources that may provide comparable results. Whether you’re an experienced researcher or just getting started with your project, understanding the reliability offered by Google Scholar is essential to ensure successful outcomes from your work. So let’s answer: how reliable is Google Scholar?
Table of Contents
How to Use Google Scholar Effectively
Advantages of Using Google Scholar
Disadvantages of Using Google Scholar
Alternatives to Google Scholar
Conclusion: How Reliable Is Google Scholar?
What Is Google Scholar?
how reliable is Google Scholar? Google Scholar is a free search engine developed by Google that enables users to find scholarly literature from journals, books, and other sources.
Google Scholar offers a vast selection of scholarly works, including journal articles, conference papers, theses, dissertations, and preprints. Google Scholar is widely used by researchers due to its sophisticated algorithms and comprehensive selection of scholarly material from various sources.
Google Scholar’s accessibility and availability provide a major benefit to researchers. With its powerful algorithms and comprehensive coverage of academic literature across all disciplines, it offers open access to millions of documents from different sources including open-access repositories like PubMed Central or arXiv – something that traditional library databases can’t offer.
With its user-friendly interface, Google Scholar enables researchers to quickly refine their searches based on various criteria such as author name or publication year, thus optimizing the research process.
Verifying the accuracy and reliability of sources can be a challenge when using Google Scholar, due to its lack of editorial oversight on many documents indexed. In addition, it only provides access to a limited number of sources compared with more comprehensive search engines like Scopus or Web Of Science. Although these may require payment for full-text access.
Google Scholar is a powerful tool for research and innovation teams to quickly access relevant information. By understanding how to use Google Scholar effectively, you can maximize its potential in your research process.
Key Takeaway: Google Scholar is a powerful search tool that offers unrestricted access to vast amounts of data from diverse origins, thus rendering it an invaluable asset for researchers. However, the accuracy and reliability of some indexed materials may be questionable due to their lack of editorial oversight and limited source accessibility.
How to Use Google Scholar Effectively
How reliable is Google Scholar? We can make it reliable by learning how to use it effectively. Using Google Scholar effectively can be a game-changer for R&D and innovation teams.
Getting set up with an account is the initial step for utilizing Google Scholar efficiently, taking only a few moments of your time. Once you have set up your account, Google Scholar’s extensive resources will be available to you.
To begin searching for relevant information, use keywords that are related to your research topic or question. You can also refine your results by using advanced search options such as language, author name, and year of publication if needed. Keeping track of all the sources you find during this process is essential to avoid duplicating work and ensure accuracy in citations when writing reports or articles later on.
Google Scholar’s convenience and breadth of resources, providing access to thousands of scholarly articles from various disciplines worldwide with just a single click, make it an ideal tool for researchers at all levels. Furthermore, its user-friendly interface makes navigation easy even for those who may not have had much experience with online databases or search engines – making it ideal for researchers at all levels.
In addition, its comprehensive coverage includes both peer-reviewed journals as well as books and conference proceedings. This ensures that no source goes undiscovered during your research process.
(Source)
Unfortunately, there are some limitations associated with using Google Scholar. This is primarily because many universities do not provide full-text access so finding complete versions can be difficult sometimes (unless they are open access).
Additionally, since most content indexed by Google scholar comes from external websites there’s always a risk involved regarding verifying accuracy and reliability, especially when citing sources in publications or reports. Lastly, a limited number of sources available could lead researchers towards missing out on important references while conducting their research projects thus hampering progress significantly over time.
Alternatives exist if you need more specific material than what’s offered through Google Scholar alone. This includes academic search engines like Scopus and Web of Science as well as library databases such as JSTOR and ProQuest. There are also open-access journals like PLOS ONE and BMC.
Each platform offers unique advantages depending on what kind of data/information one needs exactly, so make sure to explore them thoroughly before deciding which option best suits individual requirements.
Using Google Scholar effectively can save time and effort when researching topics. With its comprehensive coverage of academic literature, it is a valuable tool for R&D teams to have in their arsenal. By taking advantage of the advantages discussed above, research teams will be able to quickly access relevant information and refine their results with ease.
Key Takeaway: Google Scholar is a great asset for R&D and innovation teams, providing easy access to thousands of scholarly articles from all over the world. Although it has its limitations such as not having full-text access or difficulty verifying accuracy and reliability, there are plenty of other search engines available which can be explored depending on individual requirements. All in all, Google Scholar is an invaluable tool that shouldn’t be overlooked when conducting research.
Advantages of Using Google Scholar
Google Scholar is a powerful tool for research and innovation teams, offering comprehensive coverage of academic literature from various sources. Google Scholar enables research and development teams to remain abreast of the most recent advances in their field, providing access to a broad range of scholarly literature. Users can quickly locate pertinent data that satisfies their requirements through the user-friendly interface.
One of the main advantages of using Google Scholar is its availability and accessibility of resources. Google Scholar offers an extensive selection of resources, such as books, journals, articles, and conference proceedings which makes it a valuable research tool.
Furthermore, these resources are easily accessible as they are available online with just a few clicks away; this saves time and effort when searching for information. Google Scholar has been designed with simplicity in mind, making it easy for even those unfamiliar with search engines to use.
Another advantage offered by Google Scholar is its comprehensive coverage of academic literature across different disciplines such as science and technology, engineering and medicine, and others, thus providing valuable insights into current topics within each field or area of study.
This helps researchers stay updated with the most recent advancements in their fields while also giving them access to other related topics that could help broaden their understanding further on certain subjects or domains. Additionally, through advanced search options like filtering by author name or publication year, users can refine results according to specific criteria which makes finding relevant information easier and more efficient.
How reliable is google scholar? Overall, Google Scholar provides a convenient and accessible platform for researchers to access an abundance of academic literature. Despite its benefits, Google Scholar also has some potential drawbacks that should be considered before use; these will be explored further in the following section.
Key Takeaway: Google Scholar is a go-to platform for research and innovation teams, offering easy access to an extensive range of academic literature. It provides users with the latest information in their field through its user-friendly interface, while also allowing them to refine results by author name or publication year making it easier to find relevant data quickly and efficiently.
Disadvantages of Using Google Scholar
Though its usefulness is undeniable, one must be aware of certain drawbacks when using Google Scholar for research.
One of the main disadvantages of using Google Scholar is the limited number of sources available. While it does have an extensive collection, it only includes certain types of content such as journal articles, books, conference papers, and patents.
This platform may not provide access to other types of materials such as periodicals or magazines. Additionally, many databases are not included in Google Scholar’s search engine which can make finding relevant information more difficult than if you were searching on another platform such as Academic Search Engines or Library Databases.
Another disadvantage of using Google Scholar is verifying the accuracy and reliability of sources found within its database. Since anyone can upload their work for Google Scholar indexing, there’s no assurance that all results are valid or dependable since they have not been verified by specialists in the field before being posted online.
Therefore, users must take extra caution when evaluating results from this platform before relying on them for research purposes or making any decisions based on these findings.
How reliable is Google Scholar? Overall, it is clear that Google Scholar has some disadvantages when used as a research tool. Therefore, researchers should consider other alternatives to find reliable sources of information for their projects.
Key Takeaway: Google Scholar provides a wealth of academic literature, but is limited in its scope and reliability. Users should be aware that not all sources indexed by the platform have been vetted or verified for accuracy. Thus extra caution must be exercised when evaluating results from Google Scholar to ensure reliable research findings.
Alternatives to Google Scholar
There are other search engines and databases that can provide more comprehensive coverage of academic literature than Google Scholar. Scopus and Web of Science offer researchers a wealth of peer-reviewed journals, conference papers, book chapters, and other scholarly material. Library databases like JSTOR and ProQuest also provide access to scholarly resources from leading publishers in the humanities, sciences, social sciences, and business disciplines.
Open Access Journals such as PLOS ONE or BMC are freely available online publications with content that is published under an open license allowing readers to use the material without any restrictions. These alternatives offer researchers greater control over their searches by allowing them to refine their results according to specific criteria (e.g., publication date range).
Open Access Journals like PLOS ONE or BMC offer users the opportunity to store their searches, permitting them to monitor their progress on a given topic or research project throughout its duration. By taking advantage of these tools researchers can get better insights into the topics they’re researching while ensuring accuracy and reliability in their sources at the same time.
Research smarter, not harder. Take advantage of reliable alternatives to Google Scholar like Scopus, Web of Science & Open Access Journals for comprehensive coverage and better insights. Click to Tweet
Conclusion: How Reliable Is Google Scholar?
How reliable is Google Scholar? While it has some disadvantages such as its inability to provide full texts of articles or the need for manual sorting through results.
Overall, Google Scholar provides an invaluable resource that can be used in combination with other tools to maximize the efficiency of any team’s research process. With careful consideration and the use of alternatives when necessary, Google Scholar can help your team make informed decisions quickly and reliably.
How reliable is Google Scholar? Discover the reliability of Google Scholar with Cypris, a research platform designed to provide rapid time-to-insights for R&D and innovation teams. Uncover valuable insights quickly and efficiently by centralizing data sources into one comprehensive platform.
Keep Reading
A prompt is a single instruction issued to a language model, executed once, by one person, in a context nobody else can see. An agent is an encoded workflow with a defined scope, a defined corpus, defined evidence standards, and defined output structure, executed the same way every time regardless of who runs it. The difference between them is not sophistication. It is control.
That difference lands harder in IP than in almost any other function, because IP work product is discoverable, reviewable, and occasionally dispositive. A freedom-to-operate assessment can become an exhibit. A prior art search becomes the record of what the applicant knew and when. An invalidity position becomes the basis of a settlement posture. The question a litigator, an examiner, or an acquirer will eventually ask is not whether the analysis was good. It is how it was performed, against what, and by whom. An analysis that cannot be reproduced cannot be defended.
Most AI-assisted IP work today is prompt-based, which means most of it cannot be reproduced.
The industry has spent three years treating prompt engineering as the path to better AI output. For exploratory work, that framing holds. For the recurring, record-bearing analyses IP teams actually run, it is the wrong problem. The question is not how to write a better prompt. It is how to stop treating a repeated legal process as an improvised individual act.
What a Prompt Actually Is
Strip away the tooling and a prompt is a one-time instruction with no persistence, no version, no scope definition, and no record of what informed it.
Consider a patent attorney asking a general-purpose AI tool to surface prior art relevant to a pending claim set. The model receives the question, retrieves or recalls whatever material it has access to, applies whatever reasoning the phrasing invites, and returns a fluent answer. The attorney reads it, adjusts the phrasing, asks again, gets a different answer, and keeps the one that seems most useful.
Four things about that process deserve naming precisely.
The instruction was never written down in a form anyone else can reuse. It exists in a chat window that will be closed. The next person who needs the same search will write their own instruction, differently, and will not know how the first one was framed.
The scope was never defined. The model inferred what counted as in-scope from the phrasing, and that inference is invisible. Two colleagues asking what they believe is the same question will search materially different territory without either of them knowing it.
The evidence standard was never set. Nothing specified whether a reference required a verifiable document number, whether the number had to resolve to a real publication, or what counted as a sufficient disclosure match. The output looks equally authoritative whether it is grounded or invented, and in IP the failure mode is specific: fabricated publication numbers, misstated priority dates, and assignees inferred rather than retrieved.
And the selection was unrecorded. The attorney ran the query several times and kept the version they preferred. That is legitimate exploratory behavior. It becomes a problem the moment the retained answer informs a filing decision, a disclosure judgment, or an opinion, because the discarded runs were part of the process and no longer exist.
None of this is a criticism of the attorney. It is a description of what a prompt is. A prompt has no mechanism for carrying that structure, which is why the same person asking the same question on two different days gets two different answers with no way to explain the divergence.
What an Agent Actually Is
An agent is not a better prompt. It is a different category of artifact. The clearest statement of the difference is that an agent is written once and executed many times, whereas a prompt is written every time it is executed.
A properly constructed agent for IP work encodes five things.
It encodes the scope: the explicit boundaries of the analysis, including the technology definition, the jurisdictions searched, the date range, the claim elements under examination, adjacent art treated as in-scope, and what is deliberately excluded. Written down, identical on every execution.
It encodes the corpus: which datasets the analysis runs against and which it does not. Not an undifferentiated index the model browses at its discretion, but a defined document set with stated inclusion criteria covering patent records, non-patent literature, standards contributions, defensive publications, and whatever else the question requires.
It encodes the method: the sequence of analytical passes and the order they run in. A landscape agent runs an activity pass, an actor pass, a structural pass, a temporal pass, and a gap pass because that sequence is written into the workflow, not because a given prompt happened to invite it. An FTO agent runs claim decomposition, then independent claim mapping, then assignee normalization, then status and term verification, for the same reason.
It encodes the evidence standard: what constitutes adequate support for a finding, whether citations to source records are mandatory, and what the agent does when it cannot substantiate a conclusion. In IP this is the load-bearing component. An unverifiable reference is worse than a missing one, because it creates an illusion of completeness that discourages further searching.
And it encodes the output structure: the shape of the deliverable, so that two assessments of two different families produce comparable documents that can be reviewed side by side and docketed the same way.
The consequence is that the agent applies the same methodology regardless of who invokes it. A first-year associate and a twenty-year practitioner running the same agent on the same family get the same method. The practitioner will interpret the output better, which is exactly where their judgment should be spent. The analysis itself stops being a function of who happened to run it.
The Four Failures of Prompt-Based IP Work
The costs show up in four ways, and they compound.
Irreproducibility. A filing decision made eight months ago rested in part on an AI-assisted prior art review. Today, opposing counsel asks how that review was conducted. Under a prompt-based process the honest answer is that nobody can reconstruct it. The chat is gone, the phrasing is unrecorded, and rerunning something similar produces a different answer against a corpus that has since changed. For teams operating under a duty of candor, for anyone whose search practices may be examined in an inequitable conduct allegation, and for any organization whose IP process is subject to internal audit, this is not a minor inconvenience.
Invisible variance. When five people on an IP team each prompt their way to an answer, the organization has five methodologies it cannot see. The outputs look similar because they share a format and a tone. The rigor behind them varies enormously, and reading them will not tell you which is which. Fluency conceals variance in a way a search log never did.
Absence of an audit trail. Enterprise agent architectures now treat full audit logging as a baseline, capturing each instruction, intermediate reasoning step, model output, and tool call [1]. Prompt-based work has none of this by construction. When a reference is missed, there is no way to determine whether the failure came from the corpus, the framing, the model, or the reading, which means it cannot be prevented from recurring.
Knowledge stays with individuals. When someone becomes genuinely good at getting useful prior art out of an AI tool, that skill lives in their head. It leaves when they leave. It does not transfer to their successor, it does not raise the floor for the rest of the team, and the organization pays to develop it again. In a function where senior practitioner time is the scarcest input and outside counsel is the alternative, this is the most expensive failure of the four. Prompt skill is a personal capability. Agent configuration is an institutional asset.
Standardization Is the Actual Product
Agents in IP are usually pitched on autonomy, meaning the agent works while you sleep. That is real but secondary. The primary value is standardization, and it produces four things prompt-based work structurally cannot.
Comparability. When every family in a portfolio is assessed through the same agent, the assessments can be placed side by side and ranked. Annuity decisions, pruning decisions, and licensing prioritization all depend on comparing families against each other. Under prompt-based work, differences between two assessments reflect who ran them as much as the underlying assets, which makes portfolio-level judgment unreliable at exactly the point where the money is.
Defensibility. A general counsel, an acquirer's diligence team, or a court asking how a conclusion was reached can be shown the agent configuration, the corpus definition, the analytical sequence, and the source documents behind each finding. That is the difference between an analysis and an opinion with footnotes.
Improvability. A methodology written down can be reviewed, criticized, and revised. When a clearance search misses a reference because the corpus excluded a jurisdiction or a document type, that is a fixable configuration error and the fix applies to every future execution. When the same thing happens under prompt-based work, it is an anecdote and a claim chart nobody caught.
Institutional memory. An agent library is an encoded record of how the department does its analytical work. It is the IP equivalent of a search protocol or a docketing standard, and it accrues value the same way, by capturing what the team has learned about doing the work well.
Where Prompts Still Belong
The argument is not that prompting is obsolete. It is that prompting and agents solve different problems, and most departments are using one for both.
Prompts are right for exploration, where the question is still forming and the value comes from fast iteration. An attorney getting oriented in an unfamiliar technical area, testing whether a claim theory is worth developing, or working out how to frame an invalidity argument is doing work that a standardized workflow would slow down rather than improve. Exploratory work is supposed to be idiosyncratic.
Agents are right for any analysis that is recurring, record-bearing, or subject to review. Patent landscaping, freedom-to-operate, prior art and invalidity search, portfolio benchmarking, competitor filing monitoring, white space mapping, and IP diligence all meet at least two of those criteria, and most meet all three.
The practical test is a question: if two people in this department performed this analysis independently, would we expect the same answer, and would it matter if we did not get it? When the answer to the second part is yes, the work belongs in an agent.
The IP Function of the Next Five Years
Five shifts are already visible, and they are more structural than the current productivity framing suggests.
The practitioner role moves up a level. Execution moves into agents. Designing the analysis, auditing it, and exercising judgment on what the output means stays with people and becomes more valuable. This is not a headcount story in either direction. It is a change in what patent professionals are for. The skill that appreciates is knowing what question to ask, what evidence would answer it, and what the output is not telling you. The skill that depreciates is constructing Boolean syntax and normalizing assignee spreadsheets.
Intelligence becomes ambient rather than requested. The current model is that someone requests a landscape or a competitor update, waits weeks, and receives a document that begins aging on delivery. The agent model runs continuously and surfaces findings when they cross a defined threshold: a competitor's continuation issuing with broadened claims, a new entrant's first filing in your core CPC, an opposition deadline approaching on a family that matters. Teams stop making decisions against a stale snapshot. It also removes the request-and-wait friction that currently causes teams to skip the analysis entirely on smaller decisions, which is where quiet risk accumulates.
Methodology becomes a department asset. Organizations will maintain agent libraries the way they maintain search protocols and docketing rules, with versioning, ownership, and review cycles. How your company runs an FTO assessment becomes a documented, improvable thing rather than a set of habits held by two experienced people. This has the longest-term competitive effect, because analytical quality then compounds inside the department instead of walking out the door periodically.
Evidence standards rise. When rigorous, cited, reproducible analysis becomes cheap to produce, the bar for adequate diligence moves. Reviewers will start asking which agent produced a finding, what corpus it ran against, and when it last executed. Positions supported by an unverifiable summary will face harder questions than they do today. This is a good outcome, and it will be uncomfortable for a while.
Governance becomes the binding constraint. Most departments are underestimating this one. IBM's 2026 study found 94% of enterprises report that AI sprawl is raising security risk and operational complexity, with agents proliferating across teams and frameworks in ways that produce fragmentation rather than capability [2]. Deloitte's 2026 research found only 21% of surveyed organizations have a mature AI-agent governance model while roughly 75% intend to deploy agentic AI within two years [3]. KPMG tracked enterprise agent deployment rising from 11% to 42% over 2025 before falling back to 26% in the fourth quarter, a pullback attributed to leaders shifting from pilots toward professionalizing and scaling their agent systems [3].
That pullback is the most instructive data point in the set. It is not evidence that agents failed. It is evidence that organizations discovered the hard part is not building an agent, it is running a governed portfolio of them. For IP teams the stakes are sharper than elsewhere, because ten ungoverned agents produce ten unexaminable search histories. Departments that treat agent standardization as an operating discipline rather than a tool purchase will get through the transition without the sprawl everyone else is now consolidating.
What to Do Now
Inventory, do not purchase. Identify the analyses your department performs repeatedly and that carry consequence: landscape, FTO, prior art and invalidity, competitor monitoring, portfolio pruning, diligence support, licensing target screening.
Write down how one of them is actually performed today. Not how the protocol says it is performed, but what the person who does it actually does, including the judgment calls nobody documented. This is usually uncomfortable, because the honest version reveals how much of the method exists only in one practitioner's head.
Encode that method as an agent configuration with explicit scope, corpus, analytical sequence, evidence standard, and output structure, and treat the configuration as a versioned artifact with a named owner. If a knowledgeable colleague could read the configuration and correctly predict what the agent would flag and what it would ignore, it is specified well enough. If not, it is underspecified.
Run it in parallel with the existing process for one cycle and compare. The point is not to prove the agent is faster. It is to find where the encoded method and the human method diverge, because those divergences are where the undocumented expertise lives. Capturing them is the actual work.
How Cypris Approaches This
Cypris is built on the premise that the recurring analyses IP teams depend on should be standardized workflows rather than improvised queries. The mapping to the five components above is direct.
Method and output structure are carried by Cypris Q, the platform's agentic layer, which runs patent landscape analysis, white space mapping, freedom-to-operate, prior art research, and competitive intelligence as domain workflows. The agent already knows how to frame the question, which analytical passes to run in what order, what constitutes a finding, and how to shape the deliverable. The practitioner is not reconstructing the methodology in a prompt each time, which is precisely what makes output consistent across people and across executions.
Corpus is explicit rather than inferred. Workflows run against more than 500 million patents and scientific papers organized through a proprietary R&D ontology, and teams can scope custom corpora to a technology or a competitor set. The ontology does the work that separates a defined corpus from an undifferentiated index: it resolves terminology variation across jurisdictions, drafting conventions, and research traditions the same way every time, rather than depending on whether a given user happened to include the right synonyms.
Evidence standard is enforced at generation. Output carries citations anchored to verifiable source records, which is what allows an analysis to be checked rather than trusted.
Scope persists between runs. A configured workflow can execute continuously against new filings, literature, and corporate activity, surfacing only what meets the criteria the team defined, which turns the periodic rebuild into a maintained baseline with exception reporting.
The Underlying Point
Every organization that has industrialized a knowledge process went through the same transition, from skilled individuals doing the work their own way to a documented method executed consistently. Manufacturing did it. Clinical research did it. Software engineering did it. IP practice already did it once, when docketing stopped being a calendar in someone's office and became a system. Search and analysis is going through the same transition now, and it is being obscured by a conversation about prompting that frames an institutional problem as a personal skill.
The IP teams that will be ahead in three years are not the ones with the best prompt engineers. They are the ones that stopped needing them.
Frequently Asked Questions
What is the difference between a prompt and an AI agent in IP work?
A prompt is a single instruction executed once, with no persistent record of its scope, corpus, or evidence standard. An agent is an encoded workflow that defines scope, corpus, analytical method, evidence standards, and output structure in advance and executes the same way every time regardless of who invokes it. The difference is standardization and reproducibility, not sophistication.
Why are prompts a problem for IP analysis specifically?
IP work product is discoverable and reviewable. Prior art searches, FTO assessments, and invalidity positions may later be examined by opposing counsel, examiners, acquirers, or internal audit. Prompt-based analysis cannot be reproduced, varies invisibly between users, and generates no audit trail, which means a conclusion cannot be reconstructed or defended after the fact.
Is prompt engineering still useful for patent professionals?
Yes, for exploration, where the question is still forming and rapid iteration is the point. It is the wrong approach for analyses that recur, that inform filing or licensing decisions, or that are subject to review, because those require consistency across people and executions that a prompt cannot provide.
What makes an AI agent standardized?
It encodes five components in advance: scope including explicit inclusions and exclusions, the corpus it runs against, the sequence of analytical passes, the evidence standard governing what constitutes a supported finding, and the structure of the output. Because these are written once and executed many times, two different practitioners receive the same methodology.
Can an AI agent replace patent attorneys or analysts?
No. Agents absorb execution. Designing the analysis, auditing its output, and exercising legal judgment on what the findings mean remain human work and become more valuable. The skill that appreciates is knowing what question to ask and what the output is not showing. The skill that depreciates is constructing search syntax and cleaning assignee data.
Why are fabricated citations a bigger problem in IP than elsewhere?
Because an unverifiable reference is worse than a missing one. General-purpose models produce plausible publication numbers that do not exist, misstate priority dates, and infer assignees from context rather than retrieving them. In IP, assignee identity determines licensing strategy and risk posture, and a fabricated one creates an illusion of completeness that discourages the further searching the situation required.
What is agent sprawl and why does it matter for IP teams?
Agent sprawl is the proliferation of AI agents built independently across teams without shared governance. IBM's 2026 Institute for Business Value study found 94% of enterprises report it is raising security risk and operational complexity. For IP departments, sprawl reintroduces the exact variance problem agents were meant to solve, because ten ungoverned agents produce ten unexaminable search histories.
How mature is enterprise agent governance?
Low relative to deployment intent. Deloitte's 2026 research across more than 3,200 director-level and C-suite respondents found only 21% of organizations have a mature AI-agent governance model while approximately 75% plan to deploy agentic AI within two years. KPMG tracked deployment rising from 11% to 42% across 2025 before pulling back to 26% in the fourth quarter, attributed to leaders moving from pilots to professionalizing agent systems.
How do you turn an existing IP workflow into an agent?
Document how the analysis is actually performed today rather than how the protocol describes it. Encode that method as a configuration with explicit scope, corpus, analytical sequence, evidence standard, and output structure, treated as a versioned artifact with a named owner. Run it in parallel with the existing process for one cycle and examine where the encoded and human methods diverge, since those divergences identify the undocumented expertise that needs capturing.
What tools run standardized IP agent workflows?
Enterprise IP and R&D intelligence platforms are the category built for this. Cypris runs patent landscape analysis, white space mapping, freedom-to-operate, prior art research, and technology scouting as domain workflows through Cypris Q, its agentic layer, against a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology, with continuous execution through Agentic Monitoring and access through an MCP server, enterprise API partnerships with OpenAI, Anthropic, and Google, and Cypris Q for Microsoft Copilot.
A prompt is a single instruction issued to a language model, executed once, by one person, in a context nobody else can see. An agent is an encoded workflow with a defined scope, a defined corpus, defined evidence standards, and defined output structure, executed the same way every time regardless of who runs it. The difference between them is not sophistication. It is control.
This distinction matters more in R&D than in almost any other enterprise function, because R&D decisions carry long horizons and large capital commitments, and because the analysis behind those decisions has to survive scrutiny from stage-gate committees, IP counsel, regulators, and partners. An analysis that cannot be reproduced cannot be defended. Most AI-assisted R&D work today is prompt-based, which means most of it cannot be reproduced.
The industry conversation has spent three years on prompt engineering as the path to better AI output. For exploratory work, that framing holds. For the recurring, decision-bearing analyses that R&D organizations actually run, it is the wrong problem entirely. The question is not how to write a better prompt. It is how to stop treating a repeated organizational process as an improvised individual act.
What a Prompt Actually Is
Strip away the tooling and a prompt is a one-time instruction with no persistence, no version, no scope definition, and no record of what informed it.
Consider what happens when a research scientist asks a general-purpose AI tool to summarize the competitive position in a technology domain. The model receives the question, retrieves or recalls whatever material it has access to, applies whatever reasoning the phrasing invites, and returns a fluent answer. The scientist reads it, adjusts the phrasing, asks again, gets a different answer, and keeps the one that seems best.
Four things about that process are worth naming precisely.
The instruction was never written down in a form anyone else can reuse. It exists in a chat window that will be closed. The next person who needs the same analysis will write their own instruction, differently.
The scope was never defined. The model decided what counted as in-scope based on inference from the question, and that inference is invisible. Two colleagues asking what they believe is the same question will get answers drawn from materially different material.
The evidence standard was never set. Nothing specified whether a claim required a citation, whether the citation had to resolve to a real document, or what counted as sufficient support for a conclusion. The output looks equally authoritative whether it is grounded or invented.
And the selection was unrecorded. The scientist ran the query several times and kept the version they preferred. That is a legitimate exploratory behavior and a serious problem if the retained answer becomes an input to a funding decision, because the discarded answers were part of the process and no longer exist.
None of this is a criticism of the scientist. It is a description of what a prompt is. A prompt has no mechanism for carrying any of that structure, which is why the same person asking the same question on two different days can get two different answers and have no way to explain the divergence.
What an Agent Actually Is
An agent is not a better prompt. It is a different category of artifact, and the clearest way to understand the difference is that an agent is written once and executed many times, whereas a prompt is written every time it is executed.
A properly constructed agent for R&D work encodes five things.
It encodes the scope, meaning the explicit boundaries of what the analysis covers, including the technology domain, geography, time range, adjacent areas treated as in-scope, and areas explicitly excluded. This is written down and is the same for every execution.
It encodes the corpus, meaning which datasets the analysis runs against and which it does not. Not an undifferentiated index that the model searches at its discretion, but a defined document set with stated inclusion criteria.
It encodes the method, meaning the sequence of analytical passes the agent performs and the order it performs them in. A landscape agent runs an activity pass, an actor pass, a structural pass, a temporal pass, and a gap pass because that sequence is written into the workflow, not because a given prompt happened to invite it.
It encodes the evidence standard, meaning what constitutes adequate support for a claim, whether citations are mandatory, and what the agent does when it cannot substantiate a finding.
And it encodes the output structure, meaning the shape of the deliverable, so that two analyses of two different technology domains produce comparable documents that can be evaluated side by side.
The consequence is that an agent produces the same analysis regardless of who invokes it. A junior researcher and a twenty-year veteran running the same agent on the same question get the same methodology applied. The veteran will interpret the output better, which is where their expertise should be spent. But the analysis itself is no longer a function of who happened to run it.
The Four Failures of Prompt-Based R&D Work
The practical costs of prompt-based analysis show up in four ways, and they compound.
The first is irreproducibility. If a program was killed eight months ago based on an AI-assisted landscape analysis, and someone now asks why, the honest answer under a prompt-based process is that nobody can reconstruct it. The chat is gone, the phrasing is unrecorded, and rerunning a similar query today produces a different answer against a corpus that has since changed. For organizations in regulated industries, and for any organization where R&D decisions are subject to internal audit, this is not a minor inconvenience.
The second is invisible variance. When five people on a team each prompt their way to an answer, the organization has five methodologies it cannot see. The outputs will look similar because they share a format and a tone. The analytical rigor behind them will vary enormously, and there is no way to tell which is which by reading them. Fluency conceals variance in a way that a spreadsheet never did.
The third is the absence of an audit trail. Enterprise agent architectures now treat full audit logging as a baseline requirement, capturing each instruction, intermediate reasoning step, model output, and tool call [1]. Prompt-based work has none of this by construction. When a finding turns out to be wrong, there is no way to determine whether the error came from the corpus, the framing, the model, or the interpretation, which means the error cannot be prevented from recurring.
The fourth, and the most consequential over time, is that knowledge stays with individuals. When someone becomes genuinely good at getting useful output from AI tools for patent landscape work, that skill lives in their head. It leaves when they leave. It does not transfer to their replacement, it does not raise the floor for the rest of the team, and the organization pays to develop it again. Prompt skill is a personal capability. Agent configuration is an institutional asset.
Standardization Is the Actual Product
The value proposition of agents in R&D is usually pitched as autonomy, meaning the agent works while you sleep. That is real but secondary. The primary value is standardization, and it produces four things that prompt-based work structurally cannot.
It produces comparability. When every technology domain in a portfolio is assessed through the same agent, the resulting analyses can be placed side by side and ranked. Under prompt-based work, differences between two analyses reflect differences in who ran them as much as differences in the underlying domains, which makes portfolio-level comparison unreliable.
It produces defensibility. A stage-gate committee asking how a conclusion was reached can be shown the agent configuration, the corpus definition, the analytical sequence, and the source documents behind each claim. This is the difference between an analysis and an opinion with citations.
It produces improvability. A methodology that is written down can be reviewed, criticized, and revised. When a landscape analysis misses a competitor because the corpus excluded a jurisdiction, that is a fixable configuration error, and the fix applies to every future execution. When the same thing happens under prompt-based work, it is an anecdote.
And it produces institutional memory. An agent library is an encoded record of how an organization does its analytical work. It is the R&D equivalent of a standard operating procedure, and it accrues value in the same way, by capturing what the organization has learned about how to do the work well.
Where Prompts Still Belong
The argument is not that prompting is obsolete. It is that prompting and agents solve different problems, and most organizations are using one for both.
Prompts are the right tool for exploration, where the question itself is still forming and the value comes from fast iteration. A researcher trying to understand an unfamiliar technical area, testing whether a hypothesis is worth pursuing, or working out how to frame a problem is doing work that would be slowed down, not improved, by a standardized workflow. Exploratory work is supposed to be idiosyncratic.
Agents are the right tool for any analysis that is recurring, decision-bearing, or subject to review. Landscape analysis, freedom-to-operate assessment, prior art review, technology scouting, competitive monitoring, and portfolio evaluation all meet at least two of those three criteria, and most meet all three.
The practical test is a question: if two people on this team performed this analysis independently, would we expect the same answer, and would it matter if we did not get it? When the answer to the second part is yes, the work belongs in an agent.
The R&D Organization of the Next Five Years
Agents change what R&D teams look like, and the changes are more structural than the current productivity framing suggests. Five shifts are already visible.
The analyst role moves up a level. The work of performing analysis moves into agents. The work of designing analysis, auditing it, and interpreting it stays with people and becomes more valuable. This is not a headcount story in either direction. It is a change in what R&D analysts are for. The skill that appreciates is knowing what question to ask, what evidence would answer it, and what the output is not telling you. The skill that depreciates is executing search syntax and building charts.
Intelligence becomes ambient rather than requested. The current model is that someone asks for a landscape analysis, waits several weeks, and receives a document that begins aging on delivery. The agent model is that the analysis runs continuously and surfaces findings when they meet a defined threshold. The organizational consequence is significant: R&D teams stop making decisions against a stale snapshot and start operating with a maintained view. It also removes the request-and-wait friction that currently causes teams to skip the analysis entirely on smaller decisions.
Methodology becomes a company asset. Organizations will maintain agent libraries the way they maintain SOPs, with versioning, ownership, and review cycles. How your company runs a freedom-to-operate assessment will become a documented, improvable thing rather than a set of habits distributed across a few experienced people. This is the shift with the longest-term competitive effect, because it means analytical quality compounds within the organization instead of walking out the door periodically.
Evidence standards at stage-gate rise. When it becomes cheap to produce a rigorous, cited, reproducible analysis, the bar for what counts as adequate diligence moves. Committees will start asking which agent produced a finding, what corpus it ran against, and when it last executed. Programs supported by an unverifiable summary will face harder questions than they do today. This is a good outcome, and it will be uncomfortable for a while.
Governance becomes the binding constraint. This is the shift most organizations are underestimating. IBM's 2026 study found 94% of enterprises report that AI sprawl is raising security risk and operational complexity, with agents proliferating across teams and frameworks in ways that produce fragmentation rather than capability [2]. Deloitte's 2026 research found that only 21% of surveyed organizations have a mature AI-agent governance model while roughly 75% intend to deploy agentic AI within two years [3]. KPMG tracked enterprise agent deployment rising from 11% to 42% over 2025 before falling back to 26% in the fourth quarter, a pullback attributed to leaders shifting from pilots toward professionalizing and scaling their agent systems [3].
That pullback is the most instructive data point in the set. It is not evidence that agents failed. It is evidence that organizations discovered the hard part is not building an agent, it is running a governed portfolio of them. R&D organizations that treat agent standardization as an operating discipline rather than a tool purchase will be the ones that get through that transition without accumulating the sprawl everyone else is now trying to consolidate.
What to Do Now
The first step is an inventory, not a purchase. Identify the analyses your R&D organization performs repeatedly and that inform resource commitments. For most enterprise teams that list includes landscape analysis, freedom-to-operate, prior art review, technology scouting, competitor monitoring, and partner or acquisition screening.
The second step is to write down how one of them is actually performed today. Not how the process document says it is performed, but what the person who does it actually does. This is usually uncomfortable, because the honest version reveals how much of the method exists only in one person's judgment.
The third step is to encode that method as an agent configuration with explicit scope, corpus, analytical sequence, evidence standard, and output structure, and to treat that configuration as a versioned artifact with an owner.
The fourth step is to run it in parallel with the existing process for a cycle and compare. The point is not to prove the agent is faster. It is to find where the encoded method and the human method diverge, because those divergences are where the undocumented expertise lives, and capturing them is the actual work.
How Cypris Approaches This
Cypris is an AI-native R&D intelligence platform built around the premise that the recurring analyses R&D and IP teams depend on should be standardized workflows rather than improvised queries.
Cypris Q, the platform's agentic layer, runs patent landscape analysis, white space mapping, freedom-to-operate, technology scouting, and competitive intelligence as domain workflows rather than as raw prompts. The distinction is the one this article describes. The agent already carries the structure of the analysis, meaning it knows how to frame the question, which analytical passes to run, what constitutes a finding, and how to shape the output. A user is not responsible for reconstructing the methodology in a prompt each time, which is what makes output consistent across people and across executions.
The workflows run against a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology. The ontology matters for standardization specifically, because it means the agent resolves terminology variation across jurisdictions and research traditions the same way every time, rather than depending on whether a given user happened to include the right synonyms in their query. Teams can also configure custom corpora of patent and non-patent literature scoped to a particular domain, which makes the corpus definition an explicit, reviewable part of the workflow rather than an invisible model decision.
Output is generated with citations anchored to verifiable source records. This is the evidence standard component, and it is what allows an analysis to be checked rather than trusted.
Agentic Monitoring, launched in June 2026, is the persistence layer. It runs continuously across patent offices, scientific literature, chemical compound databases, regulatory bodies, M&A activity, product launches, grant awards, and corporate news [4]. Teams define their monitoring domains once and receive filtered, contextualized intelligence on a defined cadence. This is the operational form of the ambient intelligence shift described above, converting periodic manual rebuilds into a maintained baseline with exception reporting.
For organizations standardizing on general-purpose AI platforms, Cypris exposes the same layer through an MCP server and through enterprise API partnerships with OpenAI, Anthropic, and Google. In August 2026 the company launched Cypris Q for Microsoft Copilot, allowing teams to call Cypris agents for landscape analysis, prior art research, technology scouting, and competitive intelligence from within their existing Microsoft environment [5]. The design principle is consistent with the argument here: the general-purpose model supplies reasoning and interface, while the domain layer supplies the standardized method and the grounded corpus.
Cypris serves hundreds of enterprise customers and thousands of researchers across pharmaceuticals, chemicals, advanced materials, and electronics, with enterprise-grade security meeting Fortune 500 requirements.
The Underlying Point
Every organization that has industrialized a knowledge process went through the same transition, from skilled individuals doing the work their own way to a documented method executed consistently. Manufacturing did it. Clinical research did it. Software engineering did it. R&D intelligence is going through it now, and the transition is being obscured by a conversation about prompting that frames an organizational problem as a personal skill.
The teams that will be ahead in three years are not the ones with the best prompt engineers. They are the ones that stopped needing them.
Frequently Asked Questions
What is the difference between a prompt and an AI agent?
A prompt is a single instruction issued to a language model, executed once, with no persistent record of its scope, corpus, or evidence standard. An AI agent is an encoded workflow that defines scope, corpus, analytical method, evidence standards, and output structure in advance, and executes the same way every time regardless of who invokes it. The difference is standardization and reproducibility rather than sophistication.
Why are prompts a problem for R&D analysis specifically?
R&D decisions carry long horizons and large capital commitments, and the analyses supporting them are reviewed by stage-gate committees, IP counsel, and sometimes regulators. Prompt-based analysis cannot be reproduced, contains invisible variation between users, and generates no audit trail, which means a conclusion cannot be reconstructed or defended after the fact.
Is prompt engineering still useful?
Yes, for exploratory work where the question is still forming and rapid iteration is the point. Prompting is the wrong approach for analyses that recur, that inform resource commitments, or that are subject to review, because those require consistency across people and executions that a prompt cannot provide.
What makes an AI agent standardized?
A standardized agent encodes five components in advance: the scope of the analysis including explicit inclusions and exclusions, the corpus it runs against, the sequence of analytical passes it performs, the evidence standard governing what constitutes a supported claim, and the structure of the output. Because these are written once and executed many times, two different people running the agent receive the same methodology.
Can an AI agent replace R&D analysts?
No. Agents absorb the execution of analysis, while designing the analysis, auditing its output, and interpreting findings remain human work and become more valuable. The skill that appreciates is knowing what question to ask and what the output is not showing. The skill that depreciates is executing search syntax and producing charts.
How will AI agents change R&D teams?
Five shifts are underway: analyst work moves from performing analysis to designing and auditing it; intelligence becomes continuous rather than requested on demand; analytical methodology becomes a documented company asset rather than individual expertise; evidence standards at stage-gate reviews rise as rigorous analysis becomes cheaper to produce; and agent governance becomes the primary organizational constraint on scaling.
What is agent sprawl and why does it matter for R&D?
Agent sprawl is the proliferation of AI agents built independently across teams, functions, and frameworks without shared governance. IBM's 2026 Institute for Business Value study found 94% of enterprises report AI sprawl is raising security risk and operational complexity. For R&D organizations, sprawl reintroduces the variance problem that agents were meant to solve, because ten ungoverned agents produce the same inconsistency as ten people prompting.
How mature is enterprise agent governance?
Low relative to deployment intent. Deloitte's 2026 research across more than 3,200 director-level and C-suite respondents found only 21% of organizations have a mature AI-agent governance model while approximately 75% plan to deploy agentic AI within two years. KPMG tracked deployment rising from 11% to 42% across 2025 before pulling back to 26% in the fourth quarter, attributed to leaders moving from pilots to professionalizing agent systems.
How do you turn an existing R&D analysis into an agent?
Start by documenting how the analysis is actually performed today rather than how the process document describes it. Then encode that method as a configuration with explicit scope, corpus, analytical sequence, evidence standard, and output structure, treated as a versioned artifact with a named owner. Run it in parallel with the existing process for one cycle and examine where the encoded and human methods diverge, since those divergences identify the undocumented expertise that needs capturing.
What tools run standardized R&D agent workflows?
Enterprise R&D intelligence platforms are the category built for this. Cypris runs patent landscape analysis, white space mapping, freedom-to-operate, and technology scouting as domain workflows through Cypris Q, its agentic layer, against a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology, with continuous execution through Agentic Monitoring and access through an MCP server, enterprise API partnerships with OpenAI, Anthropic, and Google, and Cypris Q for Microsoft Copilot.
A patent landscape analysis is a structured assessment of the intellectual property and technical activity in a defined technology domain, conducted to answer a specific strategic question about where innovation is concentrated, who is driving it, and where the remaining opportunity sits. For corporate R&D teams, it is the analysis that determines which research programs get funded, which partnerships get pursued, and which technology bets get abandoned before resources are committed.
The methodology most teams still follow was designed for a different era of data volume and a different kind of tooling. It assumes a human analyst constructing Boolean queries against a patent database, exporting results to a spreadsheet, manually classifying records into technology buckets, and building charts that summarize assignee counts and filing trends over time. That process produces a deliverable, but it takes weeks, it degrades the moment new filings publish, and it answers a narrower question than the one leadership actually asked.
This guide covers the modern methodology. The two changes that matter most are that the analytical work is now performed by a curated AI agent rather than by manual query construction, and that the corpus the analysis runs against must extend well beyond patents to be strategically useful. Everything else in the process follows from those two shifts.
What a Patent Landscape Analysis Is and What It Is Not
A patent landscape analysis maps the competitive and technical structure of a technology domain using the documented innovation record. It identifies who is active, what they are working on, how their activity has changed over time, where activity clusters, and where it thins out.
It is distinct from three adjacent workflows that teams often conflate with it. A prior art search establishes whether a specific invention is novel. A freedom-to-operate analysis assesses whether commercializing a specific product would infringe active claims in target markets. A technology scouting exercise looks forward to identify emerging capabilities and potential partners. A landscape analysis is broader than the first two and more structured than the third. It produces the map that the other three operate on.
The strategic value of a landscape analysis comes from what it enables downstream. It informs portfolio strategy by showing where a company's own filings sit relative to competitors. It informs research prioritization by revealing which technical approaches are crowded and which are underexplored. It informs partnership and acquisition strategy by surfacing which organizations hold positions a company lacks. And it informs risk assessment by identifying the density of third-party claims a program will eventually have to navigate.
Why the Traditional Methodology Now Fails
Three structural problems have made manual landscape analysis unreliable for enterprise decision-making.
The first is volume. Global patent filings reached 3.7 million in 2025, the fastest annual growth since 2018, and scientific publications passed 2 million articles in the same year [1]. A technology domain that produced a manageable result set five years ago now returns volumes that exceed what a human analyst can read, let alone classify with consistency. Teams respond by narrowing the query until the result set is manageable, which reintroduces the sampling error the analysis was supposed to eliminate.
The second is vocabulary. Technical language varies across jurisdictions, research traditions, corporate filing practices, and time periods. Patent attorneys draft claims to broaden coverage, which frequently means describing a well-known technique in unfamiliar terms. A keyword-driven query finds documents that use the analyst's vocabulary and misses documents that use anyone else's. Classification codes help but were not designed to track technologies that cross established categories, which describes most of the technologies enterprises care about.
The third is latency. Patents publish eighteen months after their priority date in most jurisdictions. A landscape built exclusively on the patent record is therefore a picture of competitive positioning as it existed a year and a half ago, presented as though it describes the present. For slow-moving domains this matters less. For domains where the competitive position can shift within a single funding cycle, it produces confident conclusions about a world that no longer exists.
None of these problems are solved by running the same manual process faster. They are solved by changing what the analysis runs against and what performs the analysis.
The Case for a Multi-Dataset Corpus
The single most consequential decision in a modern landscape analysis is what goes into the corpus. Most teams treat this as settled, because the workflow is called patent landscape analysis and the obvious input is patents. That assumption is where the majority of landscape analyses go wrong.
Patent data is a record of what organizations chose to protect, filed through a legal process, published on a statutory delay. It is a high-quality signal about competitive intent, and it is incomplete in specific and predictable ways. Research published in the patentometrics literature makes the limitation explicit, noting that a comprehensive technical assessment would ideally integrate patent records with experimental, clinical, and industrial data, and that patent-only analysis is intentionally scoped to innovation trends and knowledge flows rather than to the full technical picture [2].
Consider what patent-only analysis structurally cannot see. It cannot see work that organizations deliberately keep as trade secrets, which is common in process chemistry, manufacturing methods, and formulation. It cannot see defensive publications filed specifically to block others without seeking protection. It cannot see academic and national-lab research that will become commercially relevant but has not yet been commercialized by anyone. It cannot see regulatory filings that reveal which compounds and devices are actually moving toward market. It cannot see funding activity, which is often the earliest reliable indicator that a technical approach has attracted serious capital. And it cannot see hiring, acquisition, and facility investment, which indicate where organizations are building capability ahead of any filing.
The practical consequence is that a patent-only landscape systematically overstates the position of organizations with aggressive filing strategies and understates the position of organizations that protect through secrecy or that are still upstream of commercialization. A landscape of a chemical process domain built only on patents will typically miss the most sophisticated competitors entirely, because the leading process improvements are held as trade secrets.
Scientific literature deserves particular emphasis because of the timing advantage it provides. Publications frequently surface technical developments six to eighteen months before associated patents publish, and often earlier, because academic and corporate research groups publish results well ahead of the point at which a commercial application becomes patentable. Adding literature to the corpus moves the early-warning signal forward by roughly the length of the patent publication delay, which is to say it substantially eliminates the latency problem described above.
A properly constructed corpus for enterprise landscape work therefore includes global patent records, peer-reviewed and preprint scientific literature, regulatory filings and approvals in relevant jurisdictions, grant and public funding awards, clinical or field trial registries where applicable, corporate disclosures including M&A and product launches, and where relevant, chemical structure and reaction data. The point is not to maximize volume. The point is that each dataset covers a blind spot in the others, and the strategic question the analysis is meant to answer almost always spans more than one of them.
Step One: Define the Strategic Question, Not the Technology Field
The traditional first step is scope definition: name the technology domain, set the geography, set the date range, list the competitors. That step is still necessary, but it is not the first step, and treating it as the first step is why so many landscape analyses produce a competent map that answers nothing.
Start instead with the decision the analysis exists to support. "Should we build internal capability in solid-state electrolytes or license it" is a different question from "which organizations lead in solid-state electrolytes," and the two require different corpora, different classification schemes, and different outputs. A licensing question requires depth on assignee portfolios, claim scope, and expiry timelines. A build-versus-buy question requires depth on capability signals, hiring, funding, and academic pipelines.
Write the question down before defining anything else. Then derive the technology scope, geography, time range, and competitor set from the question rather than from the technology label. Geography should be set by where commercialization will occur and where competitors manufacture, not by convenience. Time range should extend back far enough to capture the technical lineage of the approach, which for most technologies means longer than the five years teams typically default to.
Step Two: Curate the Corpus Before Curating the Agent
Once the question is defined, assemble the datasets that can answer it. This is the step that has no equivalent in the traditional methodology, and it is where most of the analytical quality is determined.
Corpus curation means deliberately selecting and scoping the document set the analysis will reason over, rather than pointing a query at an undifferentiated index. The distinction matters enormously when an AI system is doing the analysis. An agent given the entire global patent record and asked about solid-state electrolytes will retrieve a large volume of loosely related material and reason over a diluted context. An agent given a curated corpus of solid-state electrolyte patents, the relevant electrochemistry literature, the associated grant awards, and the regulatory and safety record will reason over a dense, high-signal context and produce materially better output.
This is the practical answer to the failure mode most teams experience when they try to run landscape analysis through a general-purpose AI tool. The disappointing results are usually not a reasoning failure. They are a retrieval failure. The model was never given the right material, and no amount of prompt refinement compensates for a corpus that does not contain the answer.
Curate deliberately. Include the datasets that cover your question's blind spots. Set inclusion criteria explicitly, including which jurisdictions, which document types, which date boundaries, and which classification codes or subject areas. Document what you excluded and why, because that record is what makes the analysis defensible when someone challenges a conclusion.
Step Three: Configure the Agent's Scope and Reasoning Boundaries
With the corpus set, the next step is configuring the agent that will run the analysis. This is a design exercise, not a prompting exercise, and it has four components.
The first is the strategic envelope, which is the agent's statement of what the analysis is for. This is the strategic question from step one, expressed in enough detail that the agent can distinguish a relevant finding from an interesting one. Without it, the agent optimizes for comprehensiveness and returns everything.
The second is technical and market scope, which defines the boundaries of the domain in the agent's own working vocabulary. This should include the alternative terminology, adjacent technical approaches that should be treated as in-scope, and the approaches that should be treated as out-of-scope even though they will surface. Specifying exclusions is at least as valuable as specifying inclusions.
The third is evidence priorities, which tells the agent what kinds of evidence carry weight for this particular question. A landscape supporting an acquisition decision should weight assignee-level portfolio structure and claim breadth heavily. A landscape supporting a research prioritization decision should weight publication velocity, grant activity, and technical novelty more heavily than filing counts.
The fourth is escalation criteria, which defines what constitutes a finding significant enough to surface prominently rather than list. Without escalation criteria, the agent produces a flat inventory and the human analyst has to do the prioritization work manually, which is most of the work.
A well-configured agent is one where a knowledgeable colleague could read the configuration and correctly predict what the agent would flag and what it would ignore. If the configuration does not support that prediction, it is underspecified.
Step Four: Classify Through an Ontology Rather Than a Flat Taxonomy
The classification step determines what the landscape actually shows. Traditional methodology uses either patent classification codes or a flat taxonomy the analyst constructs by hand, and both approaches struggle with the same problem: technologies that span categories get assigned to one bucket and disappear from the others.
An ontology-based approach handles this differently. Rather than assigning each document to a single category, an ontology represents the relationships between technical concepts, so a document about a solid-state electrolyte using a sulfide chemistry for an automotive application is represented as sitting at the intersection of all three, and appears correctly in any analysis touching any of them. It also resolves the vocabulary problem, because an ontology encodes that different terms across jurisdictions and research traditions refer to the same underlying concept.
This is the difference between a landscape that shows filing counts by assignee and a landscape that shows which technical approaches are converging, which is where most of the strategic value sits. Convergence is invisible in a flat taxonomy because it is a relationship rather than a category.
Step Five: Run the Analytical Passes
With corpus, configuration, and classification in place, the analysis itself runs as a series of passes over the same material, each answering a different part of the strategic question.
The activity pass establishes volume and velocity: how much work is happening in each part of the domain, and whether it is accelerating or slowing. Velocity matters more than volume, because a small but rapidly accelerating cluster is usually a stronger signal than a large stable one.
The actor pass establishes who is active and in what capacity. This should distinguish between organizations filing heavily, organizations publishing heavily, organizations receiving funding, and organizations acquiring capability, because those are four different competitive postures and a patent-only analysis collapses them into one.
The structural pass establishes how the domain is organized: which technical approaches exist, how they relate, where citation and collaboration networks concentrate, and where the boundaries between approaches are dissolving.
The temporal pass establishes how the domain has changed, which requires the analysis to distinguish between genuine shifts in research direction and artifacts of publication delay or filing strategy changes.
The gap pass identifies where activity is sparse. This is the pass that requires the most caution, and the reason is worth stating plainly. An area of the map with few patents is not automatically an opportunity. It may be sparse because the approach was tried and failed, because it is covered by trade secrets, because it is not commercially viable, or because the regulatory pathway is closed. Patent white space and commercial opportunity space are distinct concepts, and treating an empty region of the patent map as an open market is one of the most expensive errors in R&D strategy. A multi-dataset corpus is what allows the gap pass to distinguish between the two, because the literature, regulatory, and funding records will show whether anyone has tried.
Step Six: Validate Before You Synthesize
AI-generated landscape analysis is only usable if every material claim traces to a verifiable source document. This is not a theoretical concern. General-purpose language models asked patent questions will produce plausible patent numbers that do not exist, misstate priority and publication dates, and attribute filings to the wrong assignee, because they are generating from training data rather than retrieving from a live record.
Build validation into the process rather than treating it as a review step. Require that every finding carries a citation to a specific document. Spot-check a sample of citations against the source record, weighted toward the findings that will drive the decision. Verify assignee names against corporate structure, because subsidiaries, joint ventures, and post-acquisition transfers routinely fragment a single competitor's portfolio across several names and make a strong position look weak. Check the date boundaries on any trend claim, because apparent declines in recent filing activity are usually the publication delay rather than a real slowdown.
Step Seven: Synthesize Into a Decision Artifact
The output of a landscape analysis is not the map. It is the answer to the strategic question from step one, supported by the map.
The deliverable should lead with the answer and the confidence level attached to it, followed by the specific evidence that supports it, followed by what the analysis could not determine and why. That last section is what separates a credible analysis from a persuasive one. Every landscape has blind spots, and naming them is what allows the decision-maker to weight the conclusion appropriately.
Visual outputs still matter, but they should be selected to support the argument rather than produced as a standard set. A landscape supporting a build-versus-buy decision needs a capability map by organization. A landscape supporting research prioritization needs a convergence view. Producing all of them regardless of question is a habit from the era when the charts were the deliverable.
Step Eight: Convert the Analysis From an Event to a Process
A landscape analysis begins degrading the day it is delivered. New filings publish, new papers appear, competitors announce, regulators act. The traditional response is to rebuild the analysis quarterly or annually, which means the organization operates on a picture that is between one and twelve months stale, and the rebuild consumes the same effort every cycle.
The alternative is to treat the configured agent as a persistent asset. Once the corpus is curated and the agent is configured, the same configuration can run continuously, evaluating new material against the strategic question as it appears and surfacing only what meets the escalation criteria defined in step three. The initial landscape becomes the baseline, and the ongoing work becomes exception handling rather than reconstruction.
This is the largest practical return on the agent-curation approach. The configuration work in steps two and three is front-loaded and non-trivial. It pays back over every subsequent cycle, because the expensive part of the traditional process was never the searching. It was the rebuilding.
Common Failure Modes
The most common failure is scoping to the technology instead of to the decision, which produces a comprehensive map that supports no particular conclusion.
The second is corpus poverty, where the analysis runs against patents alone and reaches confident conclusions about domains where the most important activity is not patented.
The third is treating white space as opportunity, addressed above, which is the failure with the highest cost attached to it.
The fourth is unvalidated AI output, where the analysis is fluent, well-organized, and contains fabricated citations that nobody checked because the document read as authoritative.
The fifth is the assignee fragmentation error, where a competitor's position is understated because their portfolio is distributed across subsidiaries and acquisition vehicles that were never consolidated.
The sixth is treating the analysis as a deliverable rather than a capability, which guarantees the organization pays the full cost again next cycle.
Tooling for Landscape Analysis
The tools available for this work fall into three categories, and the distinction matters because they were built for different users.
Free and open resources including Google Patents, The Lens, and PQAI provide access to patent records and, in some cases, linked scholarly data. They are appropriate for verification, spot-checking, and early scoping. They do not provide the corpus curation, agent configuration, or continuous execution that enterprise landscape work requires.
Legacy professional platforms including Derwent Innovation and Orbit Intelligence from Questel provide curated patent data, sophisticated search syntax, and analytical tooling built over decades. They were designed for IP professionals conducting prosecution and litigation support work, and their strengths reflect that: claim-level precision, family management, and legal status tracking. Their limitation for landscape work is that they are patent-centric by design, and the search-and-export workflow assumes a human analyst performing the reasoning.
Enterprise R&D intelligence platforms are the category built for the methodology described in this guide, combining multi-dataset corpora with agentic execution and continuous operation.
How Cypris Supports Patent Landscape Analysis
Cypris is an AI-native R&D intelligence platform built for corporate R&D teams, IP managers, and innovation strategists conducting landscape, white space, freedom-to-operate, and technology scouting work. It is designed around the two shifts this guide describes: a corpus that extends beyond patents, and analysis performed by domain-configured agents rather than manual query construction.
The platform runs on a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology is the component that addresses the classification problem described in step four. Rather than assigning documents to flat categories, it represents relationships between technical concepts, so cross-category technologies appear correctly wherever they are relevant and terminology variation across jurisdictions and research traditions resolves to the same underlying concept. This is what allows convergence analysis, which is invisible to classification-code approaches.
Corpus curation is directly supported. Teams can configure custom corpora of patent and non-patent literature scoped to a specific technology domain and strategic question, which is the step-two work described above. Scoping retrieval before it reaches the model is the practical answer to the context degradation problem that causes general-purpose AI tools to produce diluted output on technical questions.
Cypris Q, the platform's agentic layer, runs patent landscape analysis, white space mapping, freedom-to-operate, and technology scouting as domain workflows rather than as raw queries. The distinction is that the agent already carries the structure of the analysis, so it knows how to frame a landscape question, which passes to run, and what constitutes a finding, rather than requiring the user to specify the methodology in a prompt. Output is generated with citations anchored to verifiable source records, which supports the validation requirements in step six.
Agentic Monitoring, launched in June 2026, addresses step eight. It runs continuously across patent offices, scientific literature, chemical compound databases, regulatory bodies, M&A activity, product launches, grant awards, and corporate news [3]. Teams define their monitoring domains once, and the agents deliver filtered, contextualized intelligence on a cadence that fits the workflow. In landscape terms, this converts the quarterly manual rebuild into a maintained baseline with exception reporting, and it is the mechanism by which the multi-dataset argument becomes operational rather than aspirational.
For teams that have standardized on general-purpose AI platforms, Cypris exposes the same intelligence layer through an MCP server and through enterprise API partnerships with OpenAI, Anthropic, and Google. In August 2026 the company launched Cypris Q for Microsoft Copilot, which allows enterprise teams to call Cypris agents for landscape analysis, prior art research, technology scouting, and competitive intelligence from within their existing Microsoft environment [4]. The design principle is that the base model provides the reasoning and conversational interface while the domain layer scopes retrieval and supplies the structure, which is the pattern that produces reliable output on technical questions.
Cypris serves hundreds of enterprise customers and thousands of researchers across pharmaceuticals, chemicals, advanced materials, electronics, and other technical industries, with enterprise-grade security meeting Fortune 500 requirements.
Getting Started
If your team currently rebuilds landscape analyses manually each quarter, the highest-return change is not adopting an AI tool. It is writing down the strategic question the analysis exists to answer, auditing which datasets can actually answer it, and noticing how many of them are missing from your current corpus. The agent configuration follows from that, and the continuous operation follows from the configuration.
Frequently Asked Questions
What is a patent landscape analysis?
A patent landscape analysis is a structured assessment of the intellectual property and technical activity within a defined technology domain, conducted to determine where innovation is concentrated, which organizations are driving it, how the domain has evolved, and where opportunity remains. It informs portfolio strategy, research prioritization, partnership decisions, and risk assessment for corporate R&D and IP teams.
How is a patent landscape analysis different from a freedom-to-operate analysis?
A patent landscape analysis maps the competitive and technical structure of an entire technology domain to support strategic decisions. A freedom-to-operate analysis assesses whether a specific product or process would infringe active patent claims in target markets. Landscape analysis is broad and strategic; freedom-to-operate is narrow and legal. Landscape analysis typically precedes freedom-to-operate in the R&D workflow.
What are the steps in a patent landscape analysis?
The modern methodology has eight steps: define the strategic question the analysis must answer, curate a multi-dataset corpus scoped to that question, configure the analytical agent's scope and reasoning boundaries, classify the corpus through an ontology rather than a flat taxonomy, run analytical passes covering activity, actors, structure, temporal change, and gaps, validate all findings against source documents, synthesize a decision artifact that leads with the answer, and convert the configured analysis into continuous monitoring.
Should a patent landscape analysis include non-patent data?
Yes. Patent data records what organizations chose to legally protect and publishes on a statutory delay of roughly eighteen months. It cannot capture trade secrets, defensive publications, pre-commercial academic research, regulatory activity, or funding signals. Scientific literature typically surfaces technical developments six to eighteen months before associated patents publish. A corpus including patents, scientific literature, regulatory filings, grant awards, corporate disclosures, and where relevant chemical structure data produces a materially more accurate landscape than patents alone.
Can AI conduct a patent landscape analysis?
AI can perform the analytical work in a patent landscape analysis when it is given a curated corpus and configured for the specific strategic question. Output quality depends primarily on corpus construction and agent configuration rather than on prompting. General-purpose language models querying from training data rather than retrieving from a live record will produce fabricated patent numbers, incorrect dates, and misattributed assignees, so every finding must trace to a verifiable source document.
Why do AI-generated patent landscapes often produce poor results?
The most common cause is retrieval failure rather than reasoning failure. When an AI system is pointed at an undifferentiated index rather than a curated corpus, it retrieves loosely related material and reasons over a diluted context. Scoping the corpus before retrieval reaches the model is what produces dense, high-signal output. Prompt refinement does not compensate for a corpus that does not contain the answer.
Does empty space on a patent map mean commercial opportunity?
No. Patent white space and commercial opportunity space are distinct concepts. An area with few patents may be sparse because the approach was attempted and failed, because competitors protect it through trade secrets, because the technology is not commercially viable, or because the regulatory pathway is closed. Distinguishing genuine opportunity from these alternatives requires scientific literature, regulatory records, and funding data alongside the patent record.
How often should a patent landscape analysis be updated?
Continuously, rather than on a fixed cycle. Global patent filings reached 3.7 million in 2025 and scientific publications passed 2 million articles, so a landscape begins degrading immediately after delivery. Once a corpus is curated and an agent is configured, the same configuration can evaluate new material as it publishes and surface only findings that meet defined escalation criteria, replacing periodic manual rebuilds with a maintained baseline.
Who should conduct a patent landscape analysis?
Corporate R&D directors, IP managers, innovation strategists, and technology scouting teams typically own landscape analysis, often in collaboration with internal IP counsel. The analysis supports research funding decisions, portfolio strategy, and partnership evaluation, so the owner should be close enough to those decisions to define the strategic question the analysis must answer.
What tools are used for patent landscape analysis?
Free resources including Google Patents, The Lens, and PQAI support verification and early scoping. Legacy professional platforms including Derwent Innovation and Orbit Intelligence provide curated patent data and advanced search built for IP prosecution and litigation workflows. Enterprise R&D intelligence platforms such as Cypris combine multi-dataset corpora with agentic execution and continuous monitoring, which is the tooling category aligned with the methodology described in this guide.